Design a Search Autocomplete System
5 min read- What it is: "top k" suggestions: match at the beginning of the query, return 5 ranked by historical frequency, < 100ms
- Scale: ~24,000 QPS (peak ~48,000); 0.4 GB new data/day
- Core data structure: trie, with 2 optimizations: cap prefix length + cache top k at every node → O(1) lookup
- Data pipeline: analytics logs → aggregators → workers rebuild trie (weekly) → trie DB → trie cache
- Sharding: by first character, but uneven ('c' > 'x') → analyze real distribution, shard-map manager
- Extras: AJAX, browser caching (Google: 1h), data sampling, delete filter layer, country tries in CDN
Also called "design top k" or "design top k most searched queries."
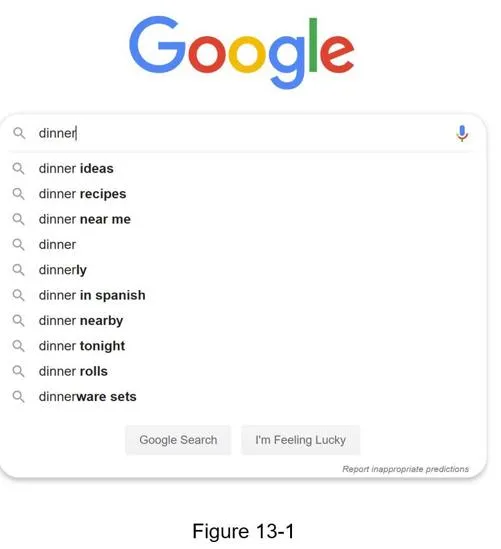
Step 1 of 4: Understand the problem and establish design scope
Goal: lock in requirements and scale numbers.
Requirements:
- Matching only at the beginning of a search query (not middle)
- Return 5 autocomplete suggestions
- Ranked by historical query frequency (popularity)
- No spell check/autocorrect
- English only, lowercase alphabetic characters
- 10 million DAU
Non-functional requirements:
- Fast response: < 100ms (otherwise UI stutters: per Facebook engineering)
- Relevant, sorted, scalable, highly available
Back of the envelope estimation:
- 10M DAU × 10 searches/day = 100M queries/day
- 20 bytes/query (4 words × 5 chars, ASCII)
- 20 requests per search (one per character typed)
- QPS: 10M × 10 × 20 / 86400 = ~24,000 QPS
- Peak QPS: ~48,000
- New data/day: 10M × 10 × 20B × 20% (new queries) = 0.4 GB
Step 2 of 4: Propose high-level design and get buy-in
Goal: split the problem: data gathering (write) + query service (read).
Data gathering service
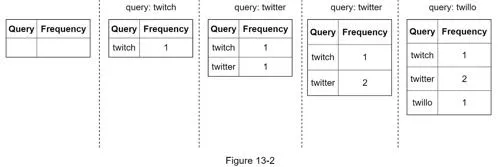
Frequency table: (query, frequency). Updated in real-time as users search.
Query service
When the user types "tw": SELECT * FROM frequency_table WHERE query LIKE 'prefix%' ORDER BY frequency DESC LIMIT 5
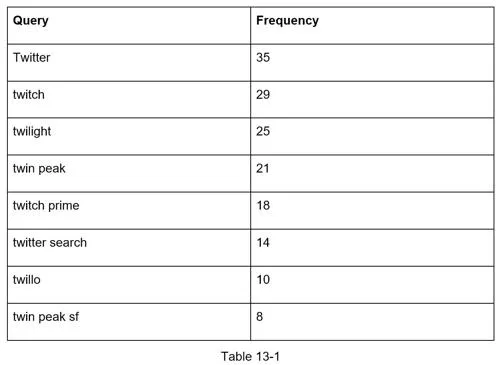
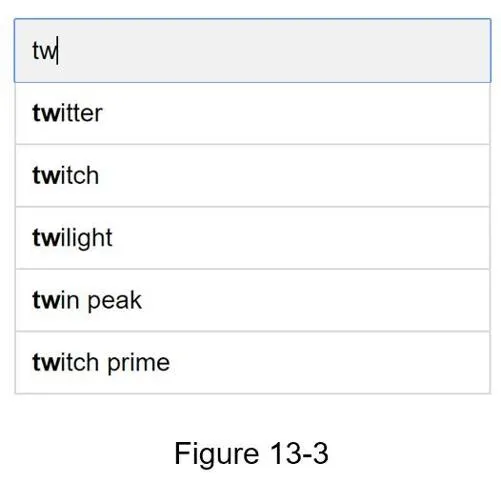
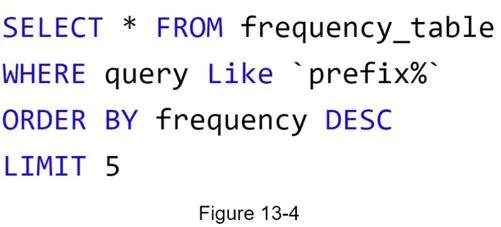
Works for small data, but the DB becomes the bottleneck at scale.
Step 3 of 4: Design deep dive
Goal: the trie, its optimizations, the async data pipeline, and sharding.
Trie data structure
Core data structure: trie (prefix tree).
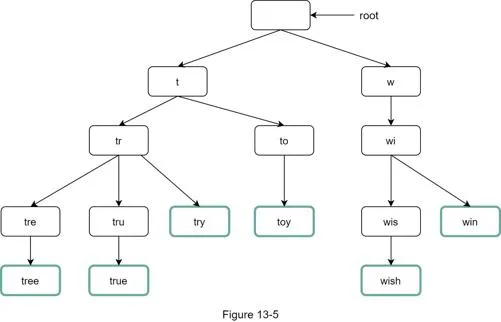
- Root = empty string
- Each node: 26 children (a-z); stores a character
- Frequency info added to nodes to support sorting
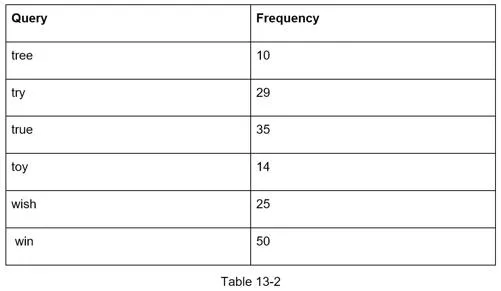
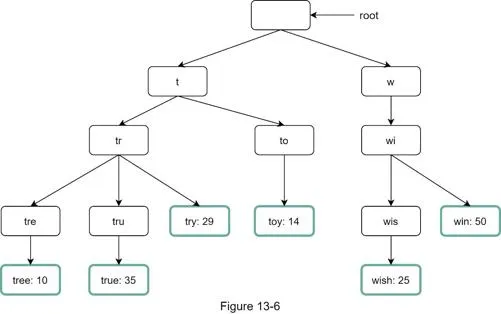
Basic trie algorithm (O(p) + O(c) + O(c log c)):
- Find prefix node: O(p)
- Traverse subtree to get all valid children: O(c)
- Sort children by frequency, get top k: O(c log c)
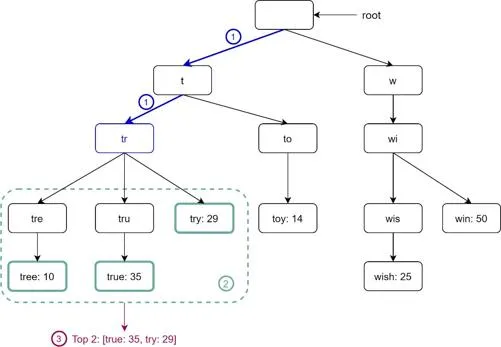
Two optimizations:
- Limit max prefix length: users rarely type > 50 chars → O(p) → O(1)
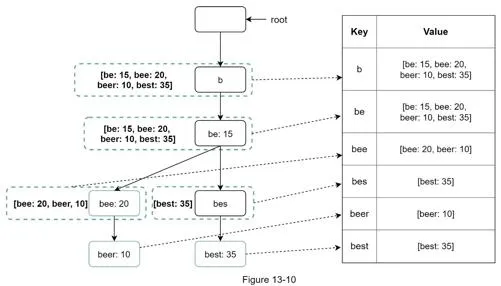
- Cache top k queries at each node: store top 5 at every node. Trades space for time
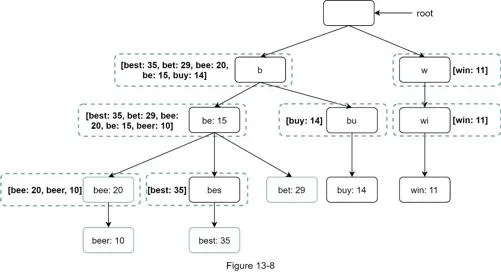
Optimized time complexity: O(1) for finding prefix + returning top k.
Data gathering service (redesigned)
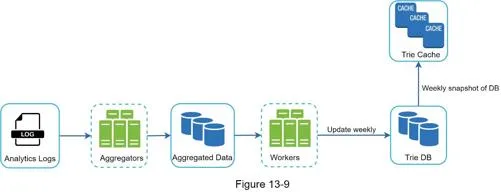
Real-time updates are impractical: billions of queries/day would slow the query service; top suggestions don't change frequently.
Components:
- Analytics Logs: append-only raw query data
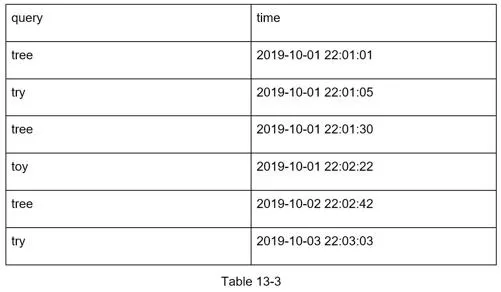
- Aggregators: aggregate data for processing. For real-time (Twitter): short intervals. For many cases: weekly is sufficient
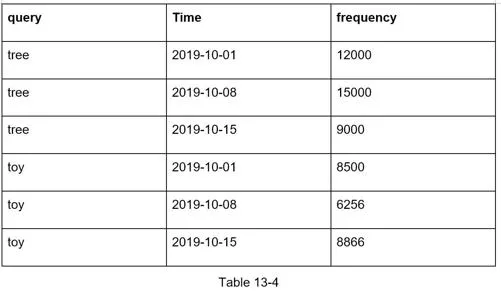
- Workers: async jobs at regular intervals; build trie, store in Trie DB
- Trie Cache: distributed in-memory cache; weekly snapshot of DB
- Trie DB: persistent storage options:
- Document store (MongoDB): serialized trie snapshot
- Key-value store: map each prefix to a hash table key, node data to value
Query service (improved)
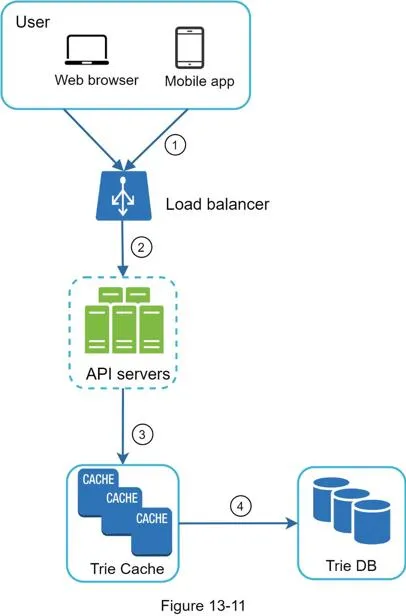
- Query → Load balancer → API servers
- API servers get trie data from Trie Cache → construct suggestions
- Cache miss → replenish from Trie DB
Optimizations:
- AJAX: no full page refresh on autocomplete
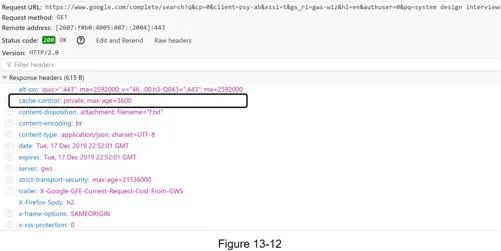
- Browser caching: cache results; Google caches for 1 hour (
max-age=3600,private)
- Data sampling: log only 1 out of every N requests
Trie operations
Create: workers build from aggregated data.
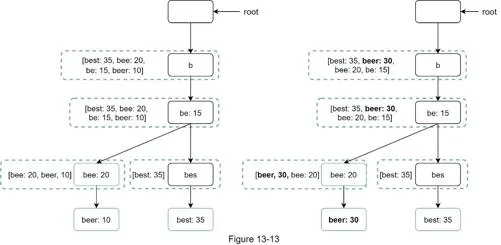
Update:
- Option 1: rebuild weekly; replace old trie
- Option 2: update individual node directly (slow; cascade-update ancestors since they cache children's top queries)
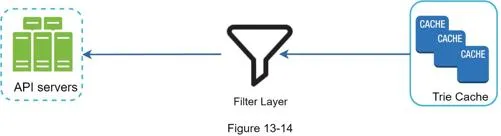
Delete: filter layer in front of Trie Cache removes unwanted suggestions (hateful, violent, explicit). Async physical removal from DB for next build cycle.
Scale the storage
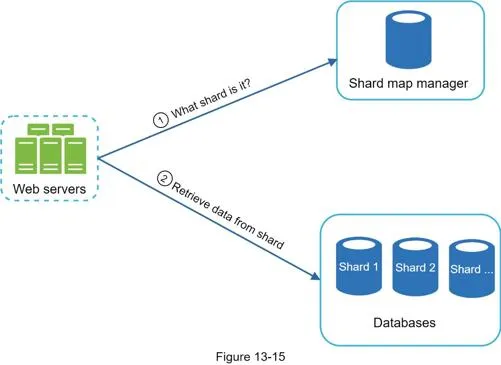
Sharding by first character (a–m, n–z) → up to 26 shards. Beyond 26: shard on second/third character. Problem: uneven distribution ('c' has more words than 'x').
Solution: analyze historical data distribution. A shard map manager maintains a lookup DB. Example: 's' alone on one shard; 'u' through 'z' combined on another.
Step 4 of 4: Wrap up
Follow-up Q&A:
- Multi-language support: store Unicode characters in trie nodes
- Country-specific top queries: build different tries per country; store in CDNs
- Trending (real-time) search queries: the original weekly rebuild doesn't work. Ideas:
- Reduce working set by sharding
- Assign more weight to recent queries in the ranking model
- Use stream processing: Hadoop MapReduce, Spark Streaming, Storm, Kafka
[1] The Life of a Typeahead Query (Facebook) [2] How We Built Prefixy [3] Prefix Hash Tree (Berkeley) [4] MongoDB wikipedia [5] Unicode FAQ [6] Apache Hadoop [7] Spark Streaming [8] Apache Storm [9] Apache Kafka